Clément Delangue 介绍以真实编程框架训练模型的开源方案
我们将 Claude Code、Codex、Hermes、Pi、@opencode 以及其他编码框架转化为 RL 环境。对框架没有做任何改动,对训练代码也没有做任何改动。任何开源模型、任何任务集,完全开源,我的各位朋友!
相同模型,相同权重:在 Mini-SWE-Agent 下为 62%,在 Claude Code 下为 33%。但在真实框架内进行训练通常意味着将其重新实现为一个环境,因此大多数模型都在一个没人实际部署的脚手架中进行训练。
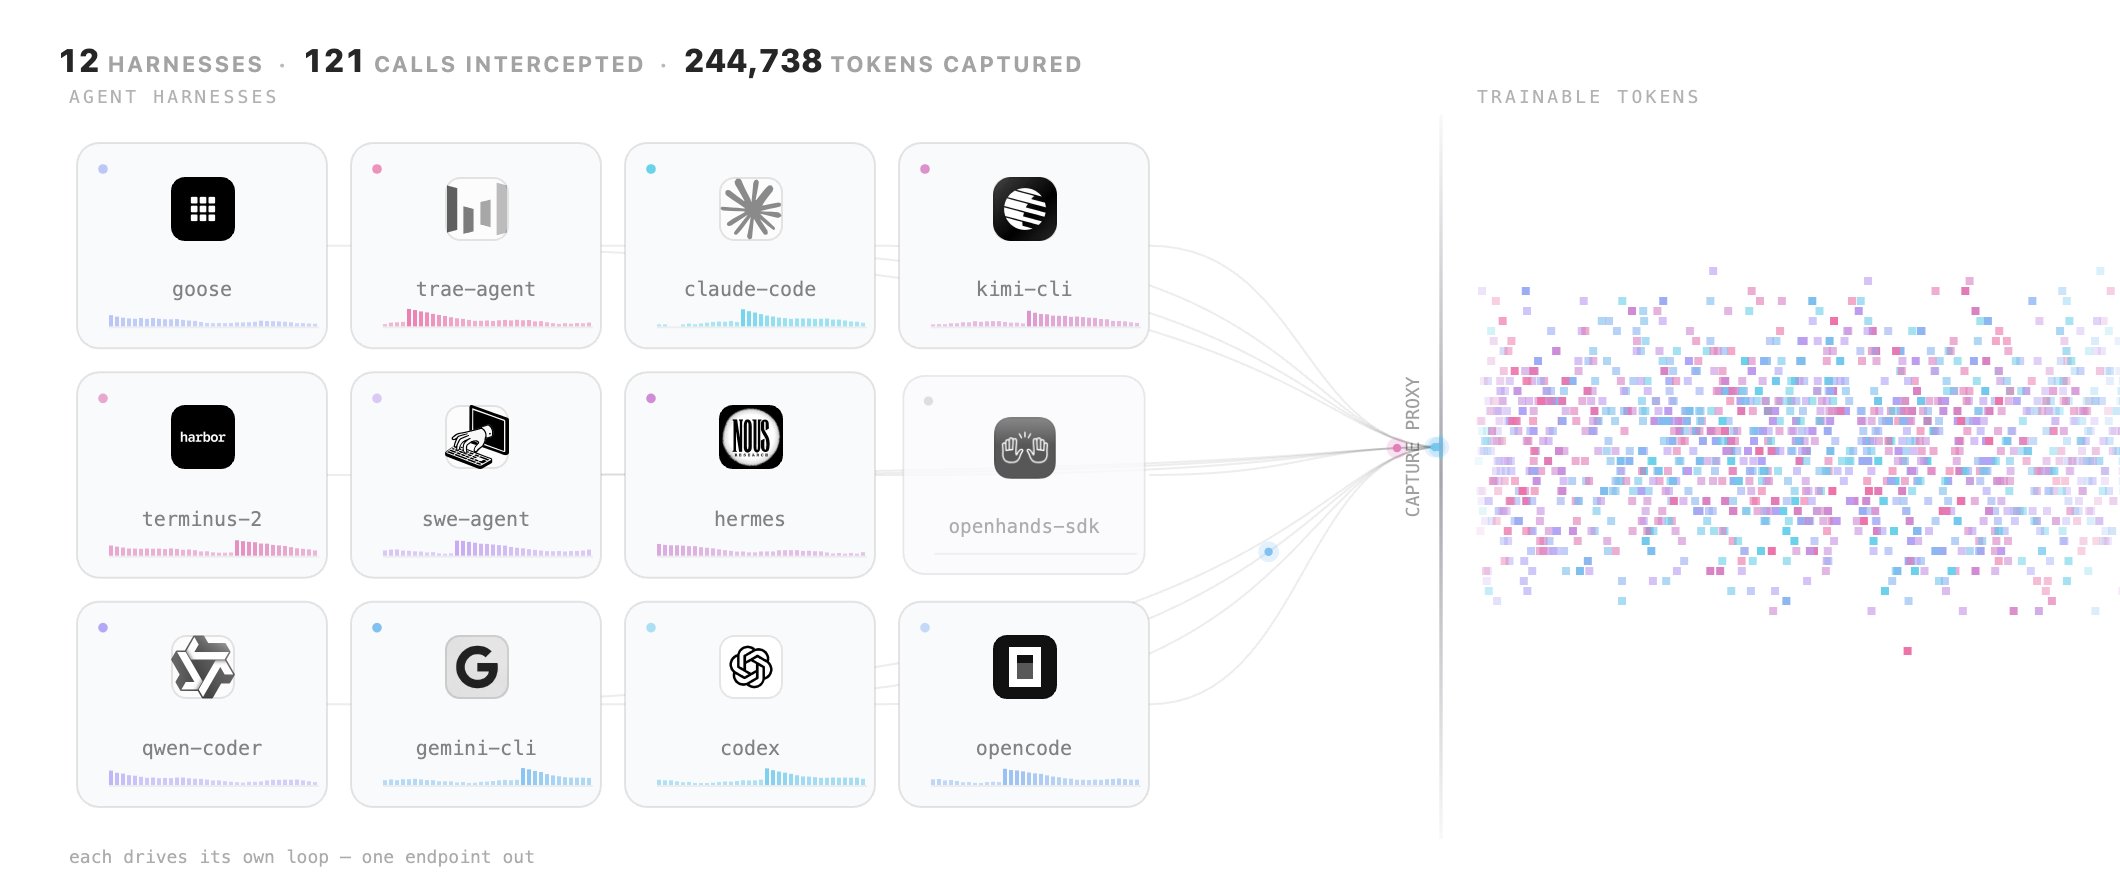
解决方案是一个代理,而不是重写。框架认为它在与模型 API 对话。它实际上是在与一个捕获代理对话,这个代理支持编码代理使用的 4 种格式(OpenAI Chat Completions、OpenAI Responses、Anthropic Messages、Gemini),将请求转发至 @vllm_project,记录 vLLM 采样的确切 token ID 和 logprobs,并将 TRL 可以训练的序列交给它。框架变成了环境。今天有 10 个框架通过它运行,没有一个被修改。
而且因为你控制奖励,你可以塑造框架从未要求的行为。我们为使用更少工具调用解决任务添加了一个小奖励:在它已经解决的任务上,模型现在在每个框架中使用 31% 更少的调用,在 Codex 下大约减半。
在 @liquidai 的 LFM2.5-2.6B 上测试: → 在一个框架中训练:主要在那个框架中更好(OpenCode 34% → 58%)。 → 同时在 4 个中训练:在所有 4 个中更好(42% → 54%)。 → 改为对来自 Qwen3.8-27B 的 3,189 次 rollout 进行 SFT:停留在 47.5%,低于两个 RL 运行。
一切都是开源且可重现的:捕获代理在 OpenEnv 中,训练器在 TRL 中,任务、SFT 数据、训练代码以及所有 7 个训练模型。接下来是更大的模型和更大的运行。
完整指南:
对照原文
We turned Claude Code, Codex, Hermes, Pi, @opencode and other coding harnesses into RL environments. No changes to the harnesses, no changes to the training code. Any open model, any task set, fully open source my friends! Same model, same weights: 62% under Mini-SWE-Agent, 33% under Claude Code. But training inside a real harness normally means reimplementing it as an environment, so most models get trained in a scaffold nobody actually ships. The fix is a proxy, not a rewrite. The harness thinks it's talking to a model API. It's actually talking to a capture proxy that speaks the 4 formats coding agents use (OpenAI Chat Completions, OpenAI Responses, Anthropic Messages, Gemini), forwards to @vllm_project, records the exact token IDs and logprobs vLLM sampled, and hands TRL sequences it can train on. The harness becomes the environment. 10 harnesses run through it today, none modified. And because you control the reward, you can shape behavior the harness never asked for. We added a small bonus for solving a task in fewer tool calls: on tasks it already solved, the model now uses 31% fewer calls, in every harness, and about half under Codex. Tested on LFM2.5-2.6B from @liquidai: → Train in one harness: better mostly in that harness (OpenCode 34% → 58%). → Train in 4 at once: better in all 4 (42% → 54%). → SFT on 3,189 rollouts from Qwen3.8-27B instead: plateaus at 47.5%, below both RL runs. Everything is open and reproducible: the capture proxy in OpenEnv, the trainer in TRL, the tasks, the SFT data, the training code and all 7 trained models. Bigger models and bigger runs next. Full guide: https://t.co/sKZURuOcza